Google Dataset Search API Documentation
The Google Dataset Search API returns the datasets Google Dataset Search finds for a query. Each result carries the dataset's title and other names, link and description, the organizations that provide and fund it, its authors, download formats and licenses, when it was last updated, the time period and areas it covers, the variables it measures and how, how many scholarly articles cite it, and a ready-made citation. Filter by update date, download format, usage rights, free access, topic, provider and Croissant format, and page through up to 200 results per query.
Pass a result's dataset_id to the
Google Dataset Info API to look that dataset up on its own later,
and its versions.versions_id as versions_id to list the dataset's other versions.
API Parameters
Search Query
-
- Name
-
q - Required
- Required
- Description
-
This parameter defines the query you want to search for datasets on Google Dataset Search, e.g.
covid casesorsea surface temperature. It can be up to 299 characters long, where most emoji count as two. Parameter is not required ifversions_idis present.
-
- Name
-
versions_id - Required
- Optional
- Description
-
This parameter lists the versions of a dataset. Take it from
versions.versions_idof a result. Google Dataset Search lists the versions whatever theq, soqcan be left out.
Filters
-
- Name
-
time_period - Required
- Optional
- Description
-
This parameter restricts results to datasets updated in the past month, year or 3 years. Supported values are
last_month,last_year, andlast_3_years.
-
- Name
-
file_formats - Required
- Optional
- Description
-
This parameter restricts results to datasets available for download in the given formats. Supported values are
tabular,document,image,text,archive,structured, andother. Separate multiple values with a comma,, e.g.tabular,archive, to get datasets in any of them.
-
- Name
-
usage_rights - Required
- Optional
- Description
-
This parameter restricts results to datasets whose license allows commercial or non-commercial use. Supported values are
commercialandnoncommercial.
-
- Name
-
is_free - Required
- Optional
- Description
-
Set this parameter to
trueto return only datasets described as free to access or under a license that allows redistribution.
-
- Name
-
topics - Required
- Optional
- Description
-
This parameter restricts results to datasets on the given topics. Supported values are
humanities,social_sciences,life_sciences,agriculture,natural_sciences,geo,computer,architecture_and_urban_planning, andengineering. Separate multiple values with a comma,, e.g.agriculture,geo, to get datasets on any of them.
-
- Name
-
provider_ids - Required
- Optional
- Description
-
This parameter restricts results to datasets from the given providers. Take the ids from the
valueof an option in thefilterswhosekeyisprovider_ids, e.g./g/11bwgw4ws7. Separate multiple values with a comma,to get datasets from any of them.
-
- Name
-
has_croissant_format - Required
- Optional
- Description
-
Set this parameter to
trueto return only datasets available in Croissant, a format for machine learning datasets.
Pagination
-
- Name
-
page - Required
- Optional
- Description
-
This parameter defines the page of results to return. Use it with
numto paginate. Google Dataset Search serves the first 200 results of a query, so(page - 1) * nummust stay under200.
-
- Name
-
num - Required
- Optional
- Description
-
This parameter defines the number of results per page, from
1to200.
Engine
-
- Name
-
engine - Required
- Required
- Description
-
Parameter defines an engine that will be used to retrieve real-time data. It must be set to
google_dataset_search.
API key
-
- Name
-
api_key - Required
- Required
- Description
-
The
api_keyauthenticates your requests. Use it as a query parameter (https://www.searchapi.io/api/v1/search?api_key=YOUR_API_KEY) or in the Authorization header (Bearer YOUR_API_KEY).
Zero Data Retention
-
- Name
-
zero_retention - Enterprise Only
- Enterprise Only
- Required
- Optional
- Description
-
Set this parameter to
trueto disable all logging and persistent storage. No request parameters, HTML, or JSON responses are stored or logged. Suitable for high-compliance use cases. Debugging and support may be limited while enabled.
API Examples
Full Response
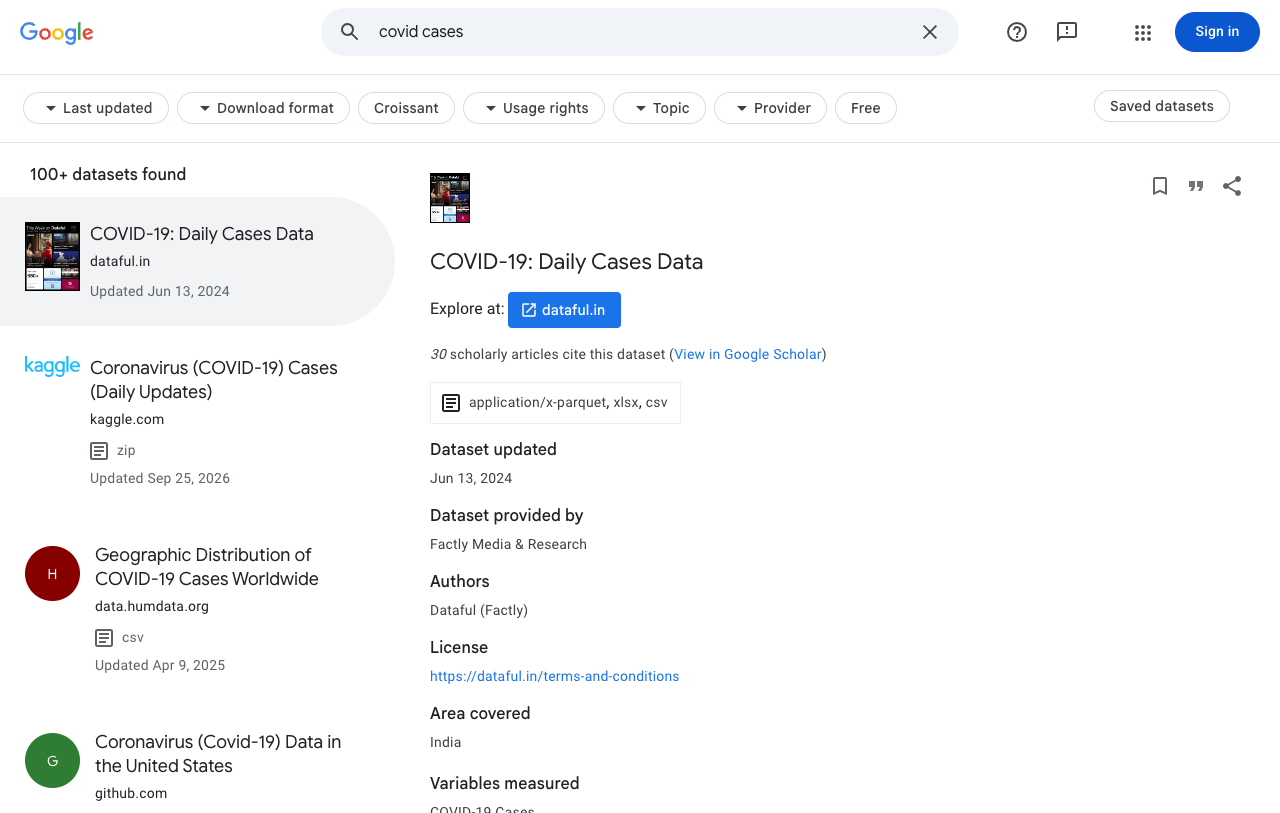
https://www.searchapi.io/api/v1/search?engine=google_dataset_search&q=covid+cases- Python
- Node
- Ruby
- Java
- Go
- PHP
- Bash
- R
- Kotlin
- Swift
- C#
- C
- C++
- requests
import requests

url = "https://www.searchapi.io/api/v1/search"
params = {
  "engine": "google_dataset_search",
  "q": "covid cases"
}

response = requests.get(url, params=params)
print(response.text)
{
  "search_metadata": {
    "id": "search_AxENYzjKgR4PcQM23D0M4GJb",
    "status": "Success",
    "created_at": "2026-11-03T10:43:07Z",
    "request_time_taken": 4.84,
    "parsing_time_taken": 0.04,
    "total_time_taken": 4.87,
    "request_url": "https://datasetsearch.research.google.com/search?query=covid+cases",
    "html_url": "https://www.searchapi.io/api/v1/searches/search_AxENYzjKgR4PcQM23D0M4GJb.html",
    "json_url": "https://www.searchapi.io/api/v1/searches/search_AxENYzjKgR4PcQM23D0M4GJb"
  },
  "search_parameters": {
    "engine": "google_dataset_search",
    "q": "covid cases",
    "page": 1,
    "num": 20
  },
  "search_information": {
    "total_results": 150
  },
  "filters": [
    {
      "key": "provider_ids",
      "options": [
        {
          "text": "Center for Disease Control & Prevention",
          "value": "/g/11npsj8pm0"
        },
        "..."
      ]
    }
  ],
  "dataset_results": [
    {
      "position": 1,
      "dataset_id": "L2cvMTFqOWNianljMw==",
      "title": "Coronavirus (Covid-19) Data in the United States",
      "link": "https://github.com/nytimes/covid-19-data",
      "domain": "github.com",
      "sources": [
        {
          "link": "https://github.com/nytimes/covid-19-data",
          "domain": "github.com"
        },
        "..."
      ],
      "description": "The New York Times is releasing a series of data files with cumulative counts of coronavirus cases in the United States, at the state and county level, over time. We are compiling this time series data from state and local governments and health departments in an attempt to provide a complete record of the ongoing outbreak.\nSince the first reported coronavirus case in Washington State on Jan. 21, 2020, The Times has tracked cases of coronavirus in real time as they were identified after testing. Because of the widespread shortage of testing, however, the data is necessarily limited in the picture it presents of the outbreak.\nWe have used this data to power our maps and reporting tracking the outbreak, and it is now being made available to the public in response to requests from researchers, scientists and government officials who would like access to the data to better understand the outbreak.\nThe data begins with the first reported coronavirus case in Washington State on Jan. 21, 2020. We will publish regular updates to the data in this repository.",
      "description_links": [
        {
          "title": "maps",
          "link": "https://www.nytimes.com/interactive/2020/us/coronavirus-us-cases.html"
        },
        "..."
      ],
      "providers": [
        {
          "name": "New York Times"
        }
      ],
      "formats": [
        {
          "format": "csv"
        }
      ],
      "licenses": [
        {
          "link": "https://github.com/nytimes/covid-19-data/blob/master/LICENSE"
        }
      ],
      "citation": "New York Times, Coronavirus (Covid-19) Data in the United States [Dataset]. https://github.com/nytimes/covid-19-data"
    },
    "..."
  ],
  "pagination": {
    "current": 1,
    "next": 2
  }
}
Filters
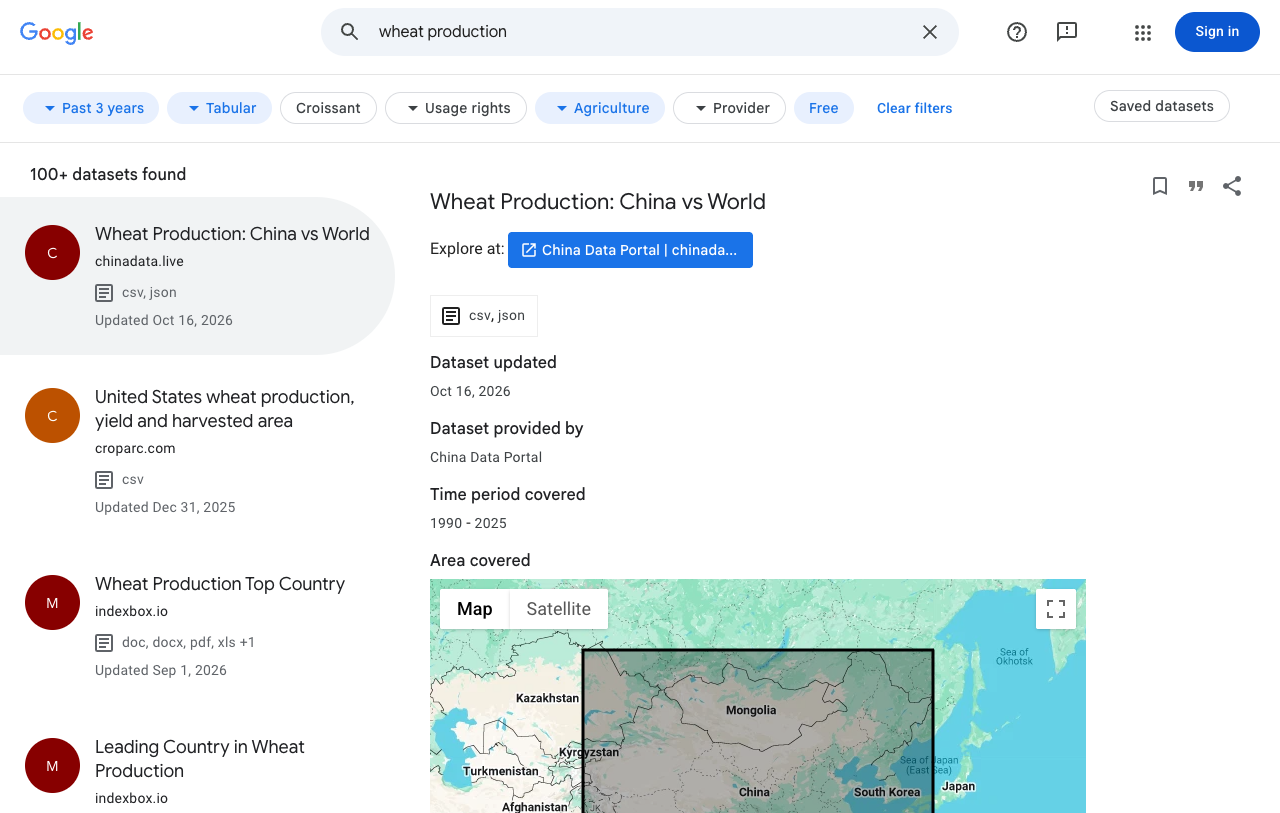
Filters combine: this search keeps tabular datasets on agriculture that are free to access and
were updated in the past 3 years. file_formats and topics take several
comma separated values.
https://www.searchapi.io/api/v1/search?engine=google_dataset_search&file_formats=tabular&is_free=true&q=wheat+production&time_period=last_3_years&topics=agriculture- Python
- Node
- Ruby
- Java
- Go
- PHP
- Bash
- R
- Kotlin
- Swift
- C#
- C
- C++
- requests
import requests

url = "https://www.searchapi.io/api/v1/search"
params = {
  "engine": "google_dataset_search",
  "q": "wheat production",
  "time_period": "last_3_years",
  "file_formats": "tabular",
  "is_free": "true",
  "topics": "agriculture"
}

response = requests.get(url, params=params)
print(response.text)
{
  "search_metadata": {
    "id": "search_ZD40AeqmorqVsD0Ngkyw25lR",
    "status": "Success",
    "created_at": "2026-11-03T10:43:12Z",
    "request_time_taken": 3.82,
    "parsing_time_taken": 0.02,
    "total_time_taken": 3.85,
    "request_url": "https://datasetsearch.research.google.com/search?query=wheat+production&filters=WyJbXCJ1cGRhdGVkX2RhdGVcIixbXCIzeVwiXV0iLCJbXCJmaWxlX2Zvcm1hdF9jbGFzc1wiLFtcIjFcIl1dIiwiW1wiaXNfYWNjZXNzaWJsZV9mb3JfZnJlZVwiXSIsIltcImZpZWxkX29mX3N0dWR5XCIsW1wiYWdyaWN1bHR1cmVcIl1dIl0%3D",
    "html_url": "https://www.searchapi.io/api/v1/searches/search_ZD40AeqmorqVsD0Ngkyw25lR.html",
    "json_url": "https://www.searchapi.io/api/v1/searches/search_ZD40AeqmorqVsD0Ngkyw25lR"
  },
  "search_parameters": {
    "engine": "google_dataset_search",
    "q": "wheat production",
    "time_period": "last_3_years",
    "file_formats": "tabular",
    "is_free": "true",
    "topics": "agriculture",
    "page": 1,
    "num": 20
  },
  "search_information": {
    "total_results": 192
  },
  "filters": [
    {
      "key": "provider_ids",
      "options": [
        {
          "text": "IndexBox Inc.",
          "value": "/g/11l6_370mn"
        },
        "..."
      ]
    }
  ],
  "dataset_results": [
    {
      "position": 1,
      "dataset_id": "L2cvMTFuangwM2drbA==",
      "title": "Wheat Production: China vs World",
      "link": "https://chinadata.live/data/wheat-production-china-vs-world/",
      "domain": "chinadata.live",
      "sources": [
        {
          "name": "China Data Portal",
          "link": "https://chinadata.live/data/wheat-production-china-vs-world/",
          "domain": "chinadata.live"
        }
      ],
      "description": "Wheat production comparison. China produces 17%+ of global wheat. Covers 1990 to 2025. Free API access available at chinadata.live",
      "providers": [
        {
          "name": "China Data Portal"
        }
      ],
      "formats": [
        {
          "format": "csv"
        },
        "..."
      ],
      "last_updated": "Oct 16, 2026",
      "extracted_last_updated": "2026-10-16",
      "period_covered": {
        "start_date": "1990",
        "end_date": "2025"
      },
      "area_covered": [
        "China"
      ],
      "geographic_coverage": {
        "bbox": [
          73.5,
          18.0,
          135.0,
          53.5
        ],
        "geometry": {
          "type": "GeometryCollection",
          "geometries": [
            {
              "type": "Polygon",
              "coordinates": [
                [
                  [
                    73.5,
                    18.0
                  ],
                  "..."
                ]
              ]
            }
          ]
        }
      },
      "variables_measured": [
        "Wheat Production: China vs World (Million Tonnes)"
      ],
      "citation": "China Data Portal (2026). Wheat Production: China vs World [Dataset]. https://chinadata.live/data/wheat-production-china-vs-world/"
    },
    "..."
  ],
  "pagination": {
    "current": 1,
    "next": 2
  }
}
Providers
The first page of a query lists the providers Google Dataset Search offers for it in filters.
Pass an option's value as provider_ids to keep to that provider's datasets, or
several values separated by commas to keep to any of them.
https://www.searchapi.io/api/v1/search?engine=google_dataset_search&provider_ids=%2Fg%2F11bwgw4ws7&q=machine+learning- Python
- Node
- Ruby
- Java
- Go
- PHP
- Bash
- R
- Kotlin
- Swift
- C#
- C
- C++
- requests
import requests

url = "https://www.searchapi.io/api/v1/search"
params = {
  "engine": "google_dataset_search",
  "q": "machine learning",
  "provider_ids": "/g/11bwgw4ws7"
}

response = requests.get(url, params=params)
print(response.text)
{
  "search_metadata": {
    "id": "search_875nmM02pVWXimJxgwE4z1Yx",
    "status": "Success",
    "created_at": "2026-11-03T10:43:17Z",
    "request_time_taken": 2.59,
    "parsing_time_taken": 0.01,
    "total_time_taken": 2.61,
    "request_url": "https://datasetsearch.research.google.com/search?query=machine+learning&filters=WyJbXCJvcmdhbml6YXRpb25fbWlkXCIsW1wiL2cvMTFid2d3NHdzN1wiXV0iXQ%3D%3D",
    "html_url": "https://www.searchapi.io/api/v1/searches/search_875nmM02pVWXimJxgwE4z1Yx.html",
    "json_url": "https://www.searchapi.io/api/v1/searches/search_875nmM02pVWXimJxgwE4z1Yx"
  },
  "search_parameters": {
    "engine": "google_dataset_search",
    "q": "machine learning",
    "provider_ids": "/g/11bwgw4ws7",
    "page": 1,
    "num": 20
  },
  "search_information": {
    "total_results": 194
  },
  "filters": [
    {
      "key": "provider_ids",
      "options": [
        {
          "text": "Growth Market Reports",
          "value": "/g/11vz41kq6y"
        },
        "..."
      ]
    }
  ],
  "dataset_results": [
    {
      "position": 1,
      "dataset_id": "L2cvMTF4ZzFnYzlidg==",
      "title": "Understanding machine learning dataset search behaviors: A survey",
      "link": "https://zenodo.org/records/15359924",
      "domain": "zenodo.org",
      "sources": [
        {
          "link": "https://zenodo.org/records/15359924",
          "domain": "zenodo.org"
        },
        "..."
      ],
      "thumbnail": "https://encrypted-tbn1.gstatic.com/images?q=tbn:ANd9GcQMFoj0uID2Il-CauN1sCByn11FnkNgKOPbGSfR7p-mhGhvakON",
      "description": "These files represent the data and accompanying documents of an independent research study by a student researcher examining the searchability and usability of machine learning dataset metadata.\n\nThe purpose of this exploratory study was to understand how machine learning (ML) practitioners are searching for and evaluating datasets for use in their work. This research will help inform development of the ML dataset metadata standard Croissant, which is actively being developed by the Croissant MLCommons working group, so it can aid ML practitioners' workflows and promote best practices like Responsible Artificial Intelligence (RAI).\n\nThe study consisted of a pre-interview Qualtrics survey (\"Survey_questions_pre_interview.pdf\") that focused on ranking various metadata elements on a Likert importance scale.\n\nThe interview consisted of open questions (\"Interview_script_and_questions.pdf\") on a range of topics from search of datasets to interoperability to AI used in dataset search. Additionally, participants were asked to share their screen at one point and recall a recent dataset search they had performed.\n\nThe resulting survey dataset (\"Survey_p1.csv\") and interview (\"Interview_p1.txt\") of participants are presented in open standard formats for accessibility. Identifying data has been removed from the files so there will be missing columns and rows potentially referenced in the files.",
      "providers": [
        {
          "name": "Zenodo",
          "link": "http://zenodo.org/",
          "thumbnail": "https://encrypted-tbn1.gstatic.com/images?q=tbn:ANd9GcQMFoj0uID2Il-CauN1sCByn11FnkNgKOPbGSfR7p-mhGhvakON"
        }
      ],
      "authors": [
        {
          "name": "Joe Edgerton"
        }
      ],
      "formats": [
        {
          "format": "pdf"
        },
        "..."
      ],
      "licenses": [
        {
          "name": "Attribution 4.0 (CC BY 4.0)",
          "link": "https://creativecommons.org/licenses/by/4.0/"
        }
      ],
      "last_updated": "May 7, 2025",
      "extracted_last_updated": "2025-05-07",
      "period_covered": {
        "start_date": "2025-05-07",
        "end_date": "2025-05-07"
      },
      "unique_identifier": "https://doi.org/10.5281/zenodo.15359924",
      "citation": "Joe Edgerton; Joe Edgerton (2025). Understanding machine learning dataset search behaviors: A survey [Dataset]. http://doi.org/10.5281/zenodo.15359924"
    },
    "..."
  ],
  "pagination": {
    "current": 1,
    "next": 2
  }
}
Versions
A dataset published in more than one version carries versions. Pass its
versions_id as versions_id to list the versions. q can be left out.
Google Dataset Search can list fewer versions than it holds.
https://www.searchapi.io/api/v1/search?engine=google_dataset_search&versions_id=1872235532649955643- Python
- Node
- Ruby
- Java
- Go
- PHP
- Bash
- R
- Kotlin
- Swift
- C#
- C
- C++
- requests
import requests

url = "https://www.searchapi.io/api/v1/search"
params = {
  "engine": "google_dataset_search",
  "versions_id": "1872235532649955643"
}

response = requests.get(url, params=params)
print(response.text)
{
  "search_metadata": {
    "id": "search_9jGd7bMw38EDuljLpmJ8v5YA",
    "status": "Success",
    "created_at": "2026-11-03T10:43:20Z",
    "request_time_taken": 1.34,
    "parsing_time_taken": 0.01,
    "total_time_taken": 1.34,
    "request_url": "https://datasetsearch.research.google.com/search?query=versions%3A&vers=1872235532649955643",
    "html_url": "https://www.searchapi.io/api/v1/searches/search_9jGd7bMw38EDuljLpmJ8v5YA.html",
    "json_url": "https://www.searchapi.io/api/v1/searches/search_9jGd7bMw38EDuljLpmJ8v5YA"
  },
  "search_parameters": {
    "engine": "google_dataset_search",
    "versions_id": "1872235532649955643",
    "page": 1,
    "num": 20
  },
  "search_information": {
    "total_results": 9
  },
  "dataset_results": [
    {
      "position": 1,
      "dataset_id": "L2cvMTF2emRoY3g2Xw==",
      "title": "Dataset: Air Quality Index (AQI) of Major Indian Cities and Stations 29/4/2024",
      "link": "https://data.mendeley.com/datasets/ys4mz7cd7y",
      "domain": "data.mendeley.com",
      "sources": [
        {
          "link": "https://data.mendeley.com/datasets/ys4mz7cd7y",
          "domain": "data.mendeley.com"
        }
      ],
      "description": "The dataset contains air quality information for various cities across India. It includes parameters such as Air Quality Index (AQI), concentrations of particulate matter (PM2.5 and PM10), ozone (O3), nitrogen dioxide (NO2), sulfur dioxide (SO2), carbon monoxide (CO), as well as geographical coordinates and time stamps. This dataset enables analysis and comparison of air quality levels among different cities, aiding in understanding environmental health impacts and informing policy decisions.",
      "authors": [
        {
          "name": "Jagadish Tawade"
        }
      ],
      "licenses": [
        {
          "name": "Attribution 4.0 (CC BY 4.0)",
          "link": "https://creativecommons.org/licenses/by/4.0/"
        }
      ],
      "last_updated": "Apr 29, 2024",
      "extracted_last_updated": "2024-04-29",
      "area_covered": [
        "India"
      ],
      "versions": {
        "versions_id": "1872235532649955643",
        "link": "https://datasetsearch.research.google.com/search?query=versions%3ADataset%3A+Air+Quality+Index+%28AQI%29+of+Major+Indian+Cities+and+Stations+29%2F4%2F2024&vers=1872235532649955643"
      },
      "unique_identifier": "https://doi.org/10.17632/ys4mz7cd7y.1",
      "citation": "Jagadish Tawade (2024). Dataset: Air Quality Index (AQI) of Major Indian Cities and Stations 29/4/2024 [Dataset]. http://doi.org/10.17632/ys4mz7cd7y.1"
    },
    "..."
  ],
  "pagination": {
    "current": 1
  }
}
Pagination
page and num page through the results, and position keeps
counting across pages. pagination.next is the next page number and is left out on the
last page. Google Dataset Search serves about 200 results per query, and its order can shift
slightly between requests, so a dataset may appear on two pages or on none.
https://www.searchapi.io/api/v1/search?engine=google_dataset_search&num=10&page=3&q=sea+surface+temperature- Python
- Node
- Ruby
- Java
- Go
- PHP
- Bash
- R
- Kotlin
- Swift
- C#
- C
- C++
- requests
import requests

url = "https://www.searchapi.io/api/v1/search"
params = {
  "engine": "google_dataset_search",
  "q": "sea surface temperature",
  "page": 3,
  "num": 10
}

response = requests.get(url, params=params)
print(response.text)
{
  "search_metadata": {
    "id": "search_lLDb6vP7p7aJu7b1oA5jqWZw",
    "status": "Success",
    "created_at": "2026-11-03T10:43:16Z",
    "request_time_taken": 1.25,
    "parsing_time_taken": 0.01,
    "total_time_taken": 1.26,
    "request_url": "https://datasetsearch.research.google.com/search?query=sea+surface+temperature",
    "html_url": "https://www.searchapi.io/api/v1/searches/search_lLDb6vP7p7aJu7b1oA5jqWZw.html",
    "json_url": "https://www.searchapi.io/api/v1/searches/search_lLDb6vP7p7aJu7b1oA5jqWZw"
  },
  "search_parameters": {
    "engine": "google_dataset_search",
    "q": "sea surface temperature",
    "page": 3,
    "num": 10
  },
  "search_information": {
    "total_results": 151
  },
  "dataset_results": [
    {
      "position": 21,
      "dataset_id": "L2cvMTF4ejhjYmJybg==",
      "title": "NOAA Sea Surface Temperature Dataset (1981-2019)",
      "link": "https://zenodo.org/records/17081473",
      "domain": "zenodo.org",
      "sources": [
        {
          "link": "https://zenodo.org/records/17081473",
          "domain": "zenodo.org"
        }
      ],
      "thumbnail": "https://encrypted-tbn1.gstatic.com/images?q=tbn:ANd9GcQMFoj0uID2Il-CauN1sCByn11FnkNgKOPbGSfR7p-mhGhvakON",
      "description": "This dataset is adapted from the NOAA Optimum Interpolation Sea Surface Temperature data, which provides monthly average temperature over 720 $\\times$ 1440 cells (i.e., 1,036,800 spatial locations). This data spans four decades, from September 1981 to December 2019.\n\nEach data file refers to a certain month with an year label, formatted as .npz. These data files can be easily loaded by NumPy in Python.\n\nWe used this dataset for large-scale seasonality quantification in climate systems. If you are interested, please check out:\n\nXinyu Chen, Vassilis Digalakis Jr, Lijun Ding, Dingyi Zhuang, Jinhua Zhao (2025). Interpretable time series autoregression for periodicity quantification. arXiv preprint arXiv:2506.22895.",
      "description_links": [
        {
          "title": "Interpretable time series autoregression for periodicity quantification",
          "link": "https://arxiv.org/abs/2506.22895"
        }
      ],
      "providers": [
        {
          "name": "Zenodo",
          "link": "http://zenodo.org/",
          "thumbnail": "https://encrypted-tbn1.gstatic.com/images?q=tbn:ANd9GcQMFoj0uID2Il-CauN1sCByn11FnkNgKOPbGSfR7p-mhGhvakON"
        }
      ],
      "authors": [
        {
          "name": "Xinyu Chen"
        }
      ],
      "formats": [
        {
          "format": "zip"
        }
      ],
      "licenses": [
        {
          "name": "Attribution 4.0 (CC BY 4.0)",
          "link": "https://creativecommons.org/licenses/by/4.0/"
        }
      ],
      "last_updated": "Sep 9, 2025",
      "extracted_last_updated": "2025-09-09",
      "unique_identifier": "https://doi.org/10.5281/zenodo.17081473",
      "citation": "Xinyu Chen; Xinyu Chen (2025). NOAA Sea Surface Temperature Dataset (1981-2019) [Dataset]. http://doi.org/10.5281/zenodo.17081473"
    },
    "..."
  ],
  "pagination": {
    "current": 3,
    "next": 4
  }
}